


70% lower token bills — your devs won’t even notice the difference
Cut monthly AI coding costs by up to 70% with ready-to-run local inference. Keep your developers’ tools and access to frontier models. Skip the DIY build.
Local inference, without the infrastructure build
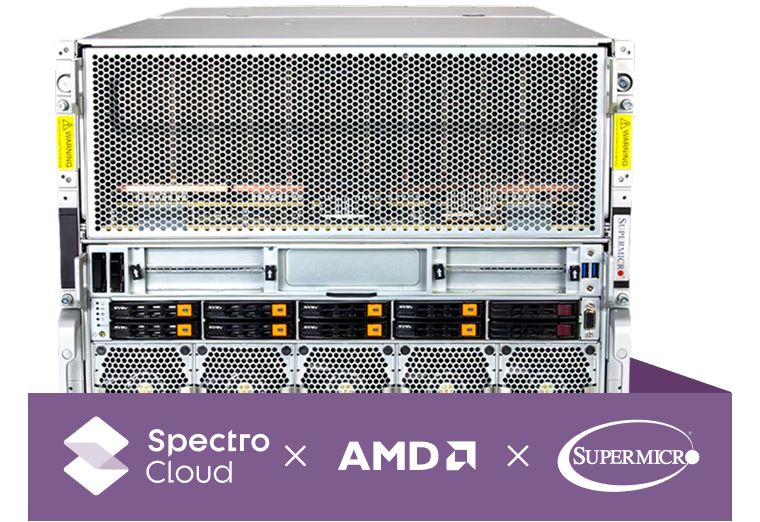
AMD Instinct Coder combines AMD GPUs, Supermicro hardware and Spectro Cloud software in a ready-to-run local coding appliance.
Because most requests execute on open models on local GPUs, your frontier bill will drop by 70% or more. Devs keep their familiar tools and won’t notice a difference in model quality. You get full policy control of cost and usage.
Best of all, it’s a fully validated stack with simple deployment and upgrades and enterprise support for the stack.
No disruption, no limits, no risk

Keep your tools.
Connect Codex, Claude Code or Cursor to your local endpoint. Developers keep their IDEs and agents.

50 developers. One node.
Each box has enough grunt for up to 50 devs with solid throughput and fast time to first token.

Keep your model options.
We ship optimized open models such as GLM-5.2 and you can bring your own. You keep access to the frontier if you need it.

Start now. Stay supported.
We have hardware in stock, with no lead time. Full-stack software support and 3-year onsite hardware support included.